A content decay monitor for blogs. It connects to Google Search Console, detects which pages are losing organic traffic using a deterministic scoring engine, and then — only for the one step that genuinely needs judgement — uses a language model to diagnose why, grounded in the live search results and the page’s actual content.
What a diagnosis actually returns
Three screenshots below are one report, read top to bottom — not three examples. This is the sample analysis the product serves on its own landing page.
It is a real run against a live blog post, not a mockup. The analysed page
appears as a path only — /blog/jade-plant-care-guide — so the site being
diagnosed stays anonymous. The competitor domains are real, named exactly as
the model named them, and were already public before this page existed.
The head of the report is the arithmetic and the summary. One click in twenty-eight days against 174 impressions at average position #54 — that is the deterministic engine’s output, and it costs nothing. Everything below it is the part that needed a model.
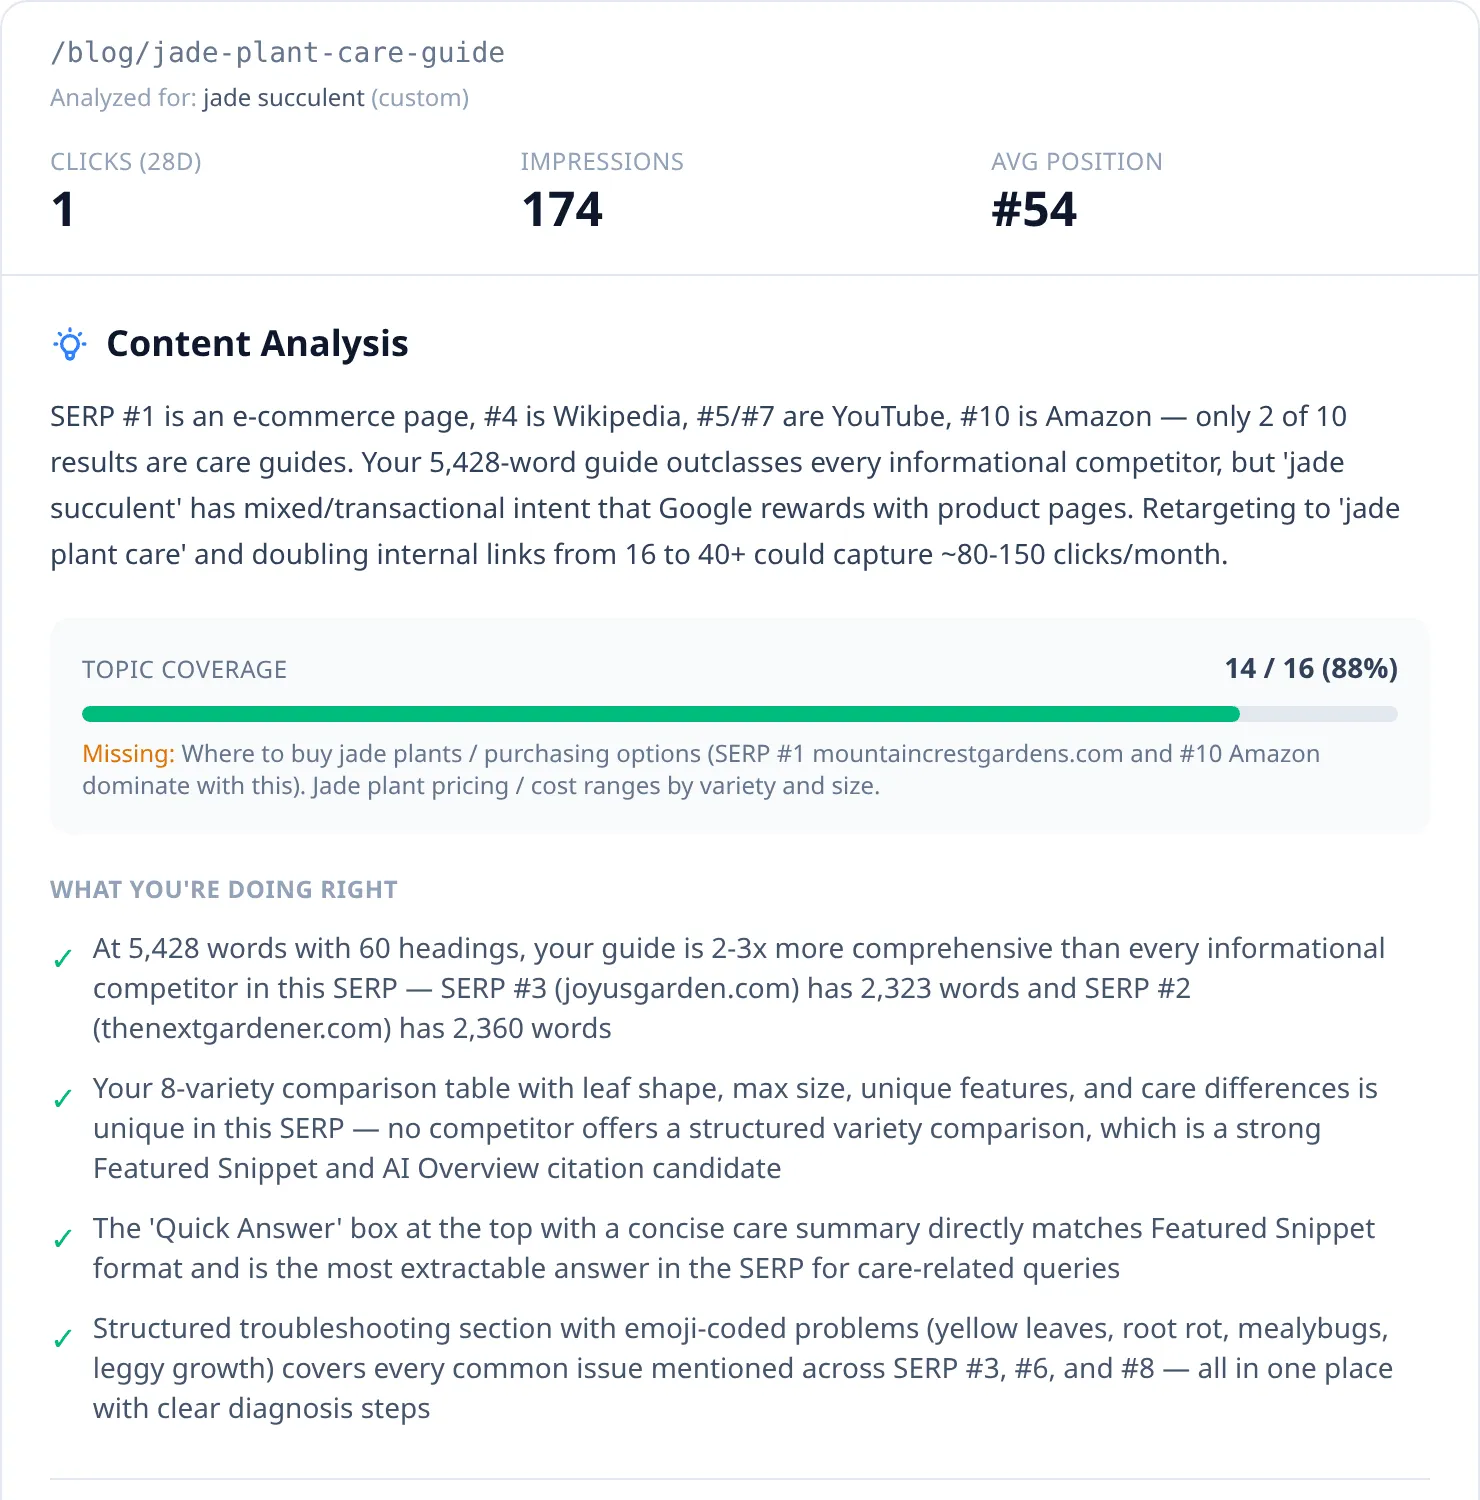
Topic coverage is the one number I would point at. 14 of 16 means the model enumerated sixteen subtopics the ranking pages collectively cover and found two missing from this one — and it says which two, with the competitor that owns each.
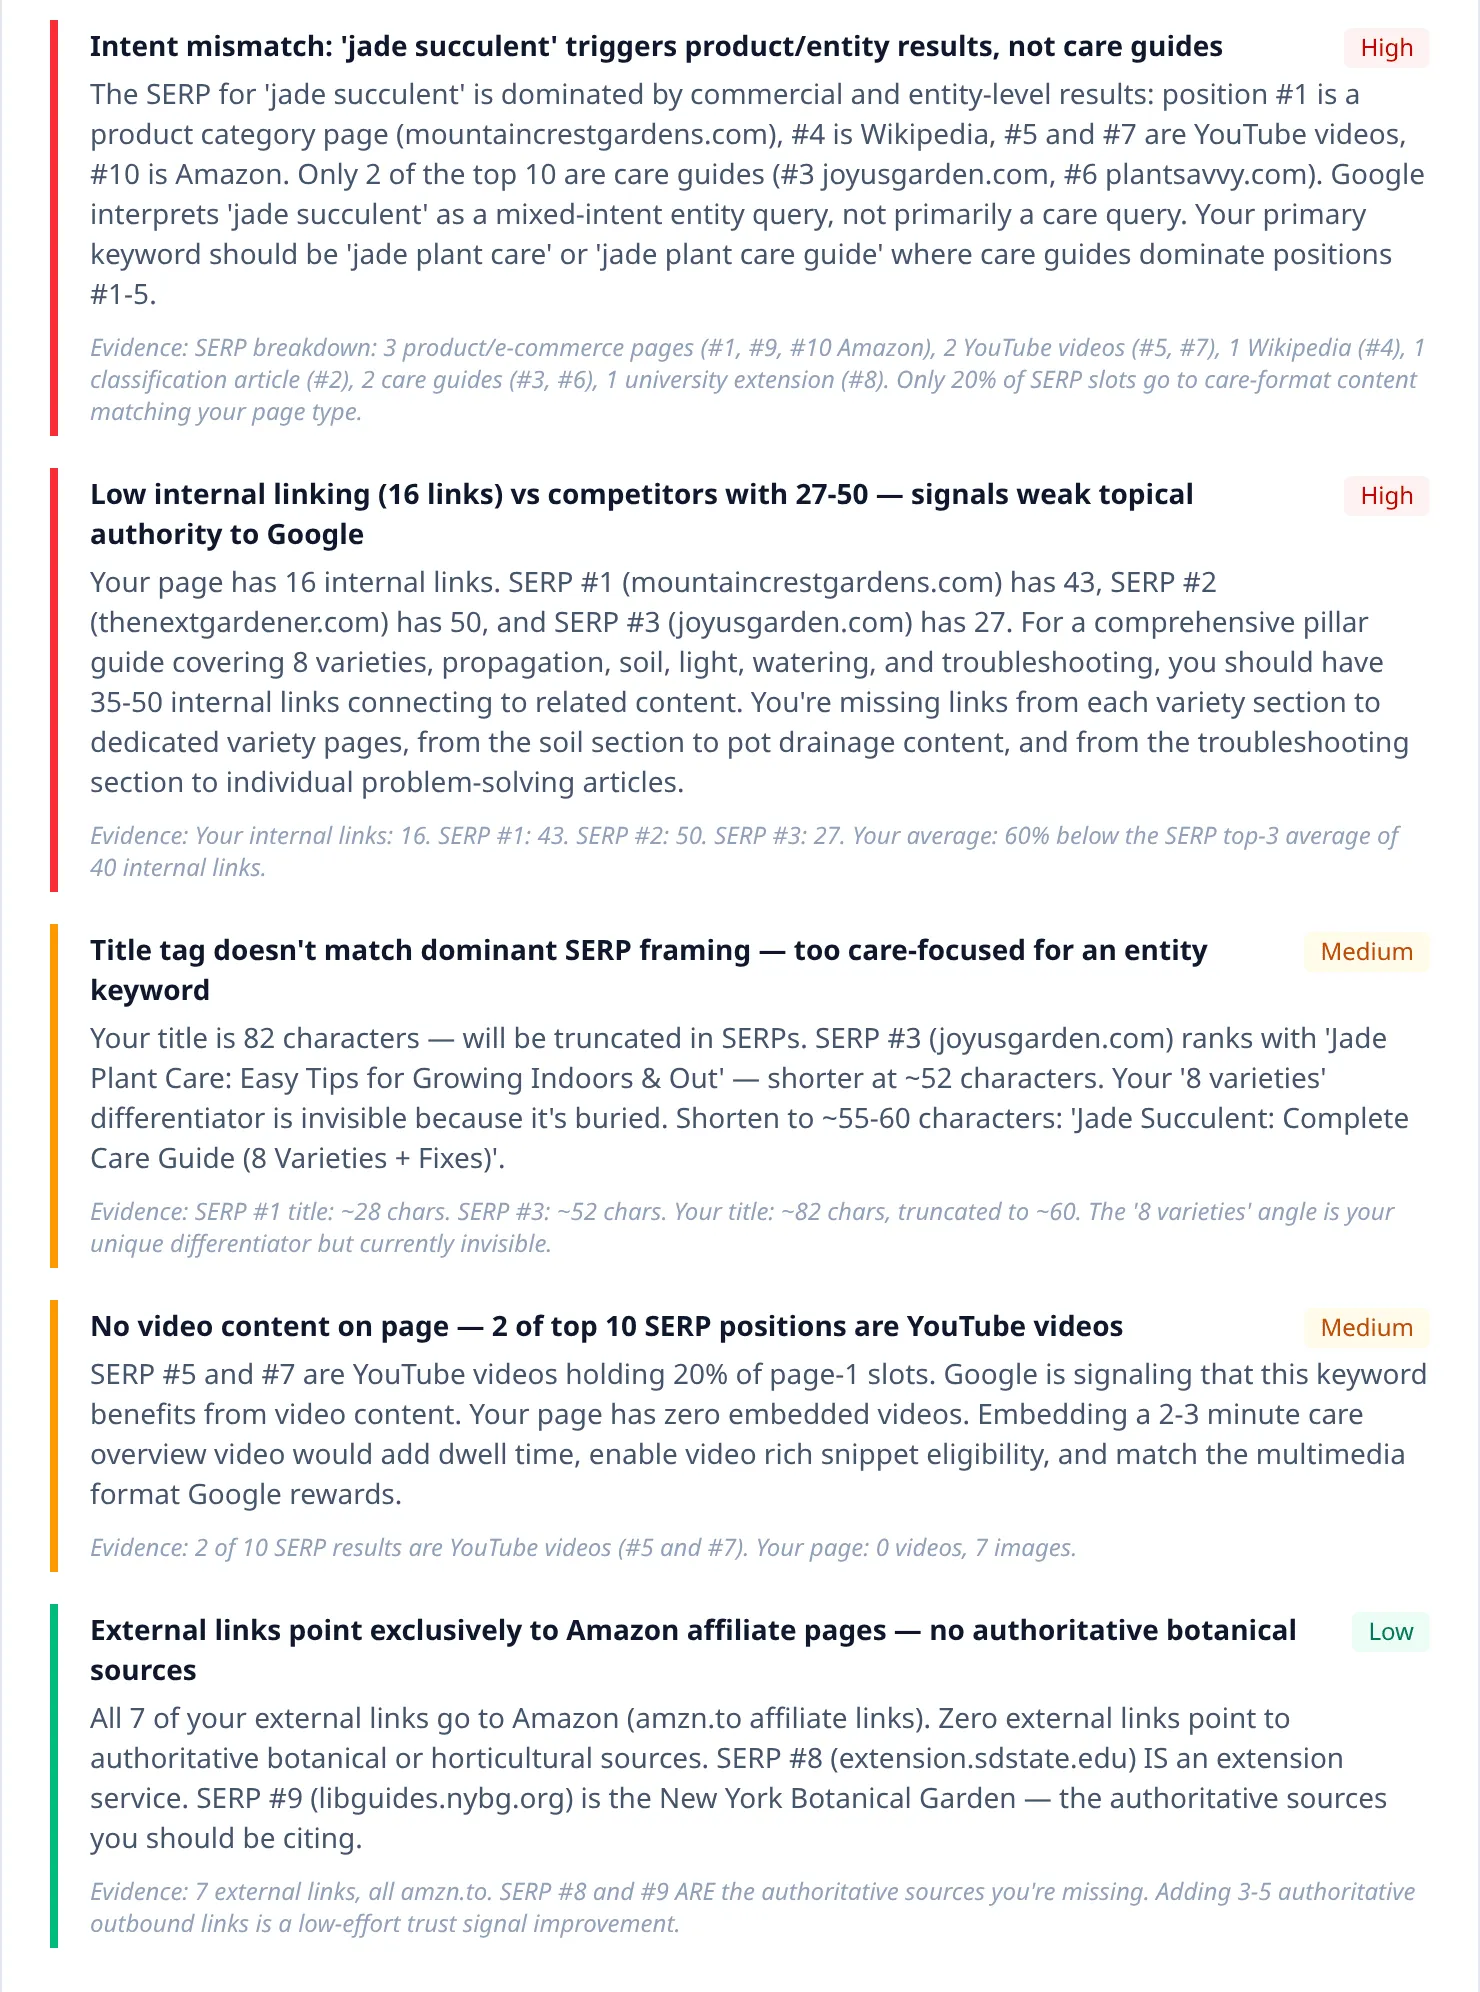
The causes are ranked and every one carries its evidence. Five of them,
High through Low, and each closes with an Evidence: line stating the counts
the judgement rests on. That line is the part I care about: a claim like “low
internal linking” is worthless without “yours 16, theirs 43, 50 and 27”.
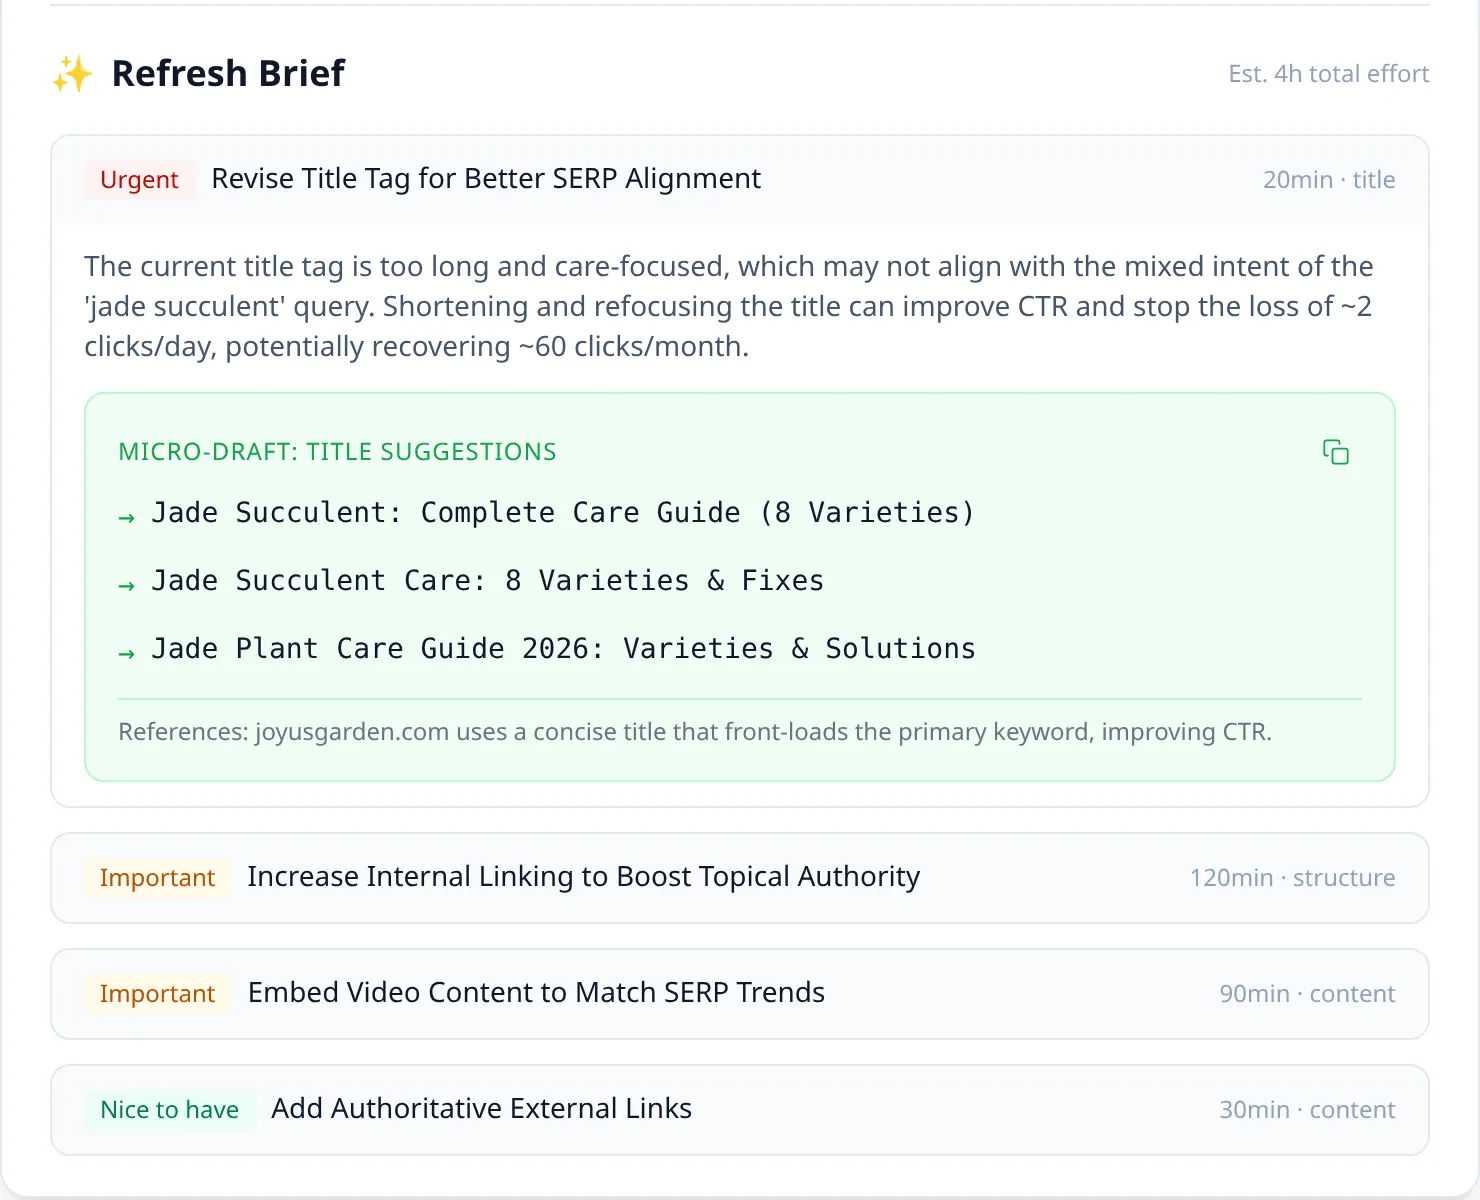
The refresh brief turns the diagnosis into work. Each action is estimated in minutes and typed by what it touches, and the urgent one expands into a micro-draft — three concrete title rewrites, with the competitor whose title shape they borrow.
That is the whole output of one paid call. The rest of this page is how it gets there, and what it costs.
There are two ways in, and the report above is only the first. That one
starts from Search Console: the engine flags a decaying page, and diagnosing it
is a deliberate second step against history the system already holds. The other
takes a URL that nothing is monitoring — api/analyze-url accepts
{ url, keyword } and nothing else, with no property to verify and no months
of data to ingest first. The two are sibling functions in the same module,
runDiagnosisPipeline and runExternalPipeline, and they diverge where you
would expect: the standalone one runs a different prompt, because there is no
traffic history to explain a decline from. It is how someone evaluates the tool
before connecting anything to it.
The problem, and where I drew the line
Bloggers and SEO consultants find decaying content by exporting Search Console data into spreadsheets and eyeballing the deltas, page by page, month after month. That work splits cleanly in two:
- Detection is arithmetic. Which pages are down, by how much, and how fast. Software should just do this.
- Diagnosis is judgement. “Why did this page lose its ranking?” requires comparing the page against what currently outranks it.
SerpVive is built along that seam. Detection is free, instant and reproducible. Diagnosis costs real money and takes minutes. Keeping them separate is what makes the product viable rather than a wrapper that bills an LLM call for subtraction.
The scoring engine is deterministic on purpose
Everything in src/lib/engine/ is pure arithmetic. No model is involved at any
point.
Decay score — (peak_clicks − current_clicks) / peak_clicks × 100, where
peak is the highest monthly click total in a 16-month window and current is
the sum of the last 28 days.
Velocity, at two resolutions — velocity_7d compares this week against last
week, velocity_28d compares the last 28 days against the 28 before that.
Positive means declining. One catches a cliff, the other catches a slide.
Seasonality check — the current 28-day window is compared against the same window one year earlier. If the ratio sits within ±20%, the page is flagged seasonal rather than decaying. This exists to kill a specific false positive: a page that predictably dips every year is not dying.
Noise filter — if the peak is under 10 monthly clicks, the score is forced to zero. Without it, a page going from 3 clicks to 1 reports as a 67% collapse and drowns the signal. A page that is growing scores zero too.
The window and the guards, from the scorer itself:
const twentyEightDaysAgo = new Date(now.getTime() - 28 * 24 * 60 * 60 * 1000)
  .toISOString()
  .slice(0, 10);
const sixteenMonthsAgo = new Date(now.getFullYear(), now.getMonth() - 16, 1)
  .toISOString()
  .slice(0, 10);src/lib/engine/decay-scorer.ts
// Calculate decay score
let decayScore = 0;
if (peakClicks >= 10 && currentClicks28d < peakClicks) {
decayScore = Math.round(((peakClicks - currentClicks28d) / peakClicks) * 10000) / 100;
}src/lib/engine/decay-scorer.tsThat one highlighted condition is both guards at once. peakClicks >= 10 is the
noise filter; currentClicks28d < peakClicks means a page that is growing
scores zero rather than a negative number that would sort strangely.
Velocity is the same arithmetic over two window pairs — this week against last, and the last 28 days against the 28 before them:
const velocity28d =
  period2Clicks > 0
    ? Math.round(((period2Clicks - period1Clicks) / period2Clicks) * 10000) /
      100
    : 0;src/lib/engine/velocity.ts
And seasonality is a ratio against the same window one year earlier, inside a ±20% band:
let isSeasonal = false;
if (lastYearClicks > 0 && currentClicks > 0) {
  const ratio = currentClicks / lastYearClicks;
  isSeasonal = ratio >= 1 - tolerance && ratio <= 1 + tolerance;
}src/lib/engine/seasonal.ts
Why no LLM here. The project has an explicit rule, written into its
CLAUDE.md before the first line of application code: never use a language
model where deterministic math works. The model is reserved for the single step
that cannot be computed — explaining why a page is losing, given the SERP, the
competitors’ content and the page itself. That boundary is the main design
decision in the whole system, and it is the reason detection can run on every
page of every site continuously while diagnosis stays a deliberate, budgeted
action.
A four-provider failover chain across three external APIs
Diagnosis calls run through a chain of four models spanning three separate providers. The ordering is not arbitrary — it escalates by blast radius, from the cheap fix to the full infrastructure swap:
flowchart TD
    START([Diagnosis request]) --> KILL{AI_DISABLED?}
    KILL -->|yes| STOP([AiDisabledError])
    KILL -->|no| CAP{Under spend cap?}
    CAP -->|no| CAPSTOP([AiSpendCapExceededError])
    CAP -->|yes| P1

    P1["1 · Claude Opus 5<br/>Anthropic"] -->|success| DONE([Diagnosis returned])
    P1 -->|"timeout 120s / error"| P2
    P2["2 · Claude Sonnet 5<br/>Anthropic — rate limits only"] -->|success| DONE
    P2 -->|fail| P3
    P3["3 · Gemini 3.7 Flash<br/>Google — survives an outage"] -->|success| DONE
    P3 -->|fail| P4
    P4["4 · GPT-5.6 Terra<br/>OpenAI — third infrastructure"] -->|success| DONE
    P4 -->|fail| EXHAUSTED([FallbackExhaustedError<br/>+ full attempt log])
Three mechanics make it work:
- A 120-second timeout per attempt, raced against the provider call. A hung provider cannot stall the chain.
- No retry on the same provider.
RETRY_SAME_PROVIDER = 0— on failure the chain moves on immediately. Retrying might recover a transient blip, but it doubles worst-case latency on an already slow pipeline for an uncertain payoff, when the next link is a known-good alternative. - Permanent errors skip ahead. Auth failures, invalid keys and billing errors are classified as non-retryable and break out immediately instead of burning the retry budget on something that cannot succeed.
Each attempt is raced against a timer, so a provider that hangs cannot hold the chain:
// Race the provider call against a timeout
const result = await Promise.race([
  provider.call(messages, options),
  new Promise<never>(
    (_, reject) => setTimeout(() => reject(new Error("TIMEOUT")), timeout)
  ),
]);src/lib/ai/fallback-chain.ts
A failure that cannot succeed on a retry is classified as permanent, so the chain stops paying for it:
function isNonRetryable(error: string): boolean {
  const lower = error.toLowerCase();
  return (
    lower.includes("401") ||
    lower.includes("403") ||
    lower.includes("invalid_api_key") ||
    lower.includes("invalid api key") ||
    lower.includes("incorrect api key") ||
    lower.includes("authentication") ||
    lower.includes("permission denied") ||
    lower.includes("model_not_found") ||
    lower.includes("model not found") ||
    lower.includes("not set") ||
    lower.includes("billing") ||
    lower.includes("quota exceeded") ||
    lower.includes("invalid_request") ||
    lower.includes("400")
  );
}src/lib/ai/fallback-chain.ts
Fourteen substring tests, which is the honest shape of it: the providers do not agree on an error taxonomy, so the classifier matches strings against their messages. It is the least elegant code on this page and I am not going to dress it up.
"not set" is highlighted because it is the one that catches a bug rather than
an outage. Each provider reads its own key inside call(), not at construction
— providers/openai.ts throws "OPENAI_API_KEY not set" there, gemini.ts
the equivalent. getDiagnosisChain() is supposed to have excluded those
providers already, so if that error ever reaches the classifier the two
disagree about what is configured. Treating it as permanent means the chain
skips the slot instead of timing out against it.
Both levels have fired in production. One diagnosis of eleven completed on
Sonnet after Opus failed — a same-provider fallback. Separately, Gemini hit its
API quota mid-brief and the chain fell through to OpenAI and completed. The
design was not theoretical; it is load-bearing, and the model_used column and
pipeline logs are where those two episodes are recorded.
A pipeline that expects malformed output
Language models return broken JSON in predictable ways, so the pipeline repairs
before it rejects. Every step below is a real branch in json-extract.ts and
diagnose.ts:
flowchart TD
    RAW([Raw model response]) --> S1

    subgraph EXTRACT["1 · Extract and repair — json-extract.ts"]
        direction TB
        S1[Strip markdown fences] --> S2[Slice to outermost braces]
        S2 --> P1{Parses?}
        P1 -->|no| S4[Escape newlines<br/>drop trailing commas]
        S4 --> P2{Parses?}
        P2 -->|no| S6[Close unbalanced brackets]
        S6 --> P3{Parses?}
    end

    P1 -->|yes| PRE
    P2 -->|yes| PRE
    P3 -->|yes| PRE
    P3 -->|no| FAIL([Unrecoverable])

    PRE["2 · Truncate to 5 causes"] --> ZOD{"3 · Zod validation"}
    ZOD -->|valid| STORE([Diagnosis stored])
    ZOD -->|invalid| RETRY["4 · Error-informed retry"]
    RETRY --> ZOD2{Valid now?}
    ZOD2 -->|yes| STORE
    ZOD2 -->|no| GIVEUP([Reject])
Two steps of the ladder, as they are written:
// Step 1: Remove markdown code fences
let cleaned = text.replace(/```(?:json)?\s*/g, "").replace(/```/g, "");

// Step 2: Find the JSON object boundaries
const firstBrace = cleaned.indexOf("{");
const lastBrace = cleaned.lastIndexOf("}");src/lib/ai/json-extract.ts
// Step 5: Try to fix truncated JSON by closing open brackets
const openBraces = (fixedTruncated.match(/{/g) ?? []).length;
const closeBraces = (fixedTruncated.match(/}/g) ?? []).length;
for (let i = 0; i < openBrackets - closeBrackets; i++) {
fixedTruncated += "]";
}
for (let i = 0; i < openBraces - closeBraces; i++) {
fixedTruncated += "}";
}src/lib/ai/json-extract.tsThose two highlighted lines are what recovers a diagnosis that hit the output token limit mid-object: the model stopped talking, and the brackets get closed for it rather than the whole run being thrown away.
The retry is worth singling out. It does not simply ask again — it hands the model back its own broken output together with the precise validation errors. And the pre-validation truncation exists because a model returning six good causes when the schema allows five is not a failure worth paying for a second call to fix.
Untrusted input is sanitised on the way in. Scraped pages, competitor
content and Search Console queries all pass through sanitize.ts before they
reach a prompt, and model output is sanitised for XSS vectors before it is
stored or rendered. The honest provenance: this was not foresight. A security
audit flagged unsanitised external content in prompts as the top vulnerability —
a competitor could embed hidden instructions in their own HTML — and the module
is the fix.
Schema and data
- 13 tables in PostgreSQL (Supabase), with row-level security on every one. The service role used by crons and webhooks bypasses RLS deliberately; everything user-facing goes through it.
- 30 versioned SQL migrations, applied in filename order.
- 42,784 Search Console query rows ingested, across 188 real monitored
pages. One site alone accounts for roughly 22,000 rows in
page_queries.
Row-level security is not one setting, it is a policy per table per operation. One of the thirty migrations, in full:
ALTER TABLE public.external_analyses ENABLE ROW LEVEL SECURITY;

CREATE POLICY "Users can view own external analyses"
  ON public.external_analyses FOR SELECT
  USING (auth.uid() = user_id);

CREATE POLICY "Users can insert own external analyses"
  ON public.external_analyses FOR INSERT
  WITH CHECK (auth.uid() = user_id);

CREATE POLICY "Users can delete own external analyses"
  ON public.external_analyses FOR DELETE
  USING (auth.uid() = user_id);supabase/migrations/20260313_add_external_analyses.sql
auth.uid() is the caller’s id taken from their JWT, so Postgres refuses
another user’s rows whatever the application asks for. Crons and webhooks use
the service role, which bypasses RLS deliberately — and that key never reaches
the browser.
Instrumentation and cost control
Every AI call logs tokens_input, tokens_output, cost_usd and
processing_time_ms to the database. That is not decoration — it is the input
to three controls:
- A global spend ceiling.
AI_SPEND_CAP_USDsums recorded cost across diagnoses, external analyses and demos and refuses new calls past the limit. It is deliberately approximate, because a run’s cost is only known once it finishes, and deliberately fails open: if the lookup errors, the call proceeds. A budget guard that becomes a single point of failure has traded a few dollars for an outage. - A single kill switch.
AI_DISABLEDstops every AI call at the one funnel they all pass through, leaving the dashboard, ingestion, scoring and email untouched. - An inactivity policy that bounds data growth. An abandoned account keeps
ingesting Search Console data forever; the API is free but Postgres is not
infinite. Accounts nobody has opened in 60 days move to a
dormantstatus and the daily cron skips them. Logging back in reactivates them automatically — nothing to request, nothing deleted.
The measured numbers above come from the previous model generation (Opus 4.6 / Sonnet 4.6): 11 production diagnoses, $0.2177 average cost per diagnosis, ~213 s average end-to-end latency. The chain now points at the current generation and has not been re-measured. The latency is not a request-response path — a diagnosis searches Google live, crawls the page plus up to three ranking competitors, and generates up to 8,192 output tokens before validation.
Running it yourself
This is not a clone-and-run project, and it would be dishonest to present it as one. Before anything renders you need a Google Cloud project with OAuth credentials for Search Console, a Supabase project with thirty migrations applied, and API keys for two paid third-party services. Budget an evening, not ten minutes.
What you need first
| Prerequisite | What it costs |
|---|---|
| Supabase project | Free tier is enough. The schema is thirty migrations. |
| Google Cloud OAuth client | Free, but the Search Console consent screen has to be configured, and you must own a verified property to have any data to read. |
| Anthropic API key | Paid per call. A diagnosis averaged $0.2177 on the previous model generation. |
| Serper.dev key | Paid per search. One diagnosis is one SERP fetch. |
| Firecrawl key | Optional. Without it the fetcher falls back to Cheerio, which cannot see JavaScript-rendered pages. |
| Gemini / OpenAI keys | Optional. The chain silently skips any provider whose key is unset, so you can run on Anthropic alone. |
Setup
git clone https://github.com/levimbraga/serpvive.git
cd serpvive
npm install
cp .env.example .env.local
Apply the migrations to your Supabase project in filename order — they are timestamped, so sorting by name is chronological:
ls supabase/migrations/*.sql | sort # 30 files, 20260309_… through 20260820_…supabase/migrationsThey are plain SQL. Paste them into the Supabase SQL editor in that order, or run them with the Supabase CLI. Order matters: later migrations add columns to tables the earlier ones create.
Then:
npm run dev # http://localhost:3000The environment
I checked this the only way worth checking it: every process.env.X in the
source, against every line the file declares. Nothing the code reads is
missing. The gap runs the other way — .env.example declares
NEXT_PUBLIC_STRIPE_PUBLISHABLE_KEY, and docs/ARCHITECTURE.md repeats it,
but no line of the application reads it. Checkout is server-side through
stripe/checkout; the publishable key is a leftover. Anyone setting the
project up would go and fetch a key they do not need.
The ones that decide whether the app boots at all:
| Variable | Purpose |
|---|---|
NEXT_PUBLIC_SUPABASE_URL, NEXT_PUBLIC_SUPABASE_ANON_KEY | Client and auth. Nothing works without them. |
SUPABASE_SERVICE_ROLE_KEY | Server-side admin client for crons and pipelines. Bypasses RLS — never expose it to the browser. |
GOOGLE_CLIENT_ID, GOOGLE_CLIENT_SECRET, GOOGLE_REDIRECT_URI | The Search Console OAuth flow. The redirect URI must match the Google console exactly. |
ANTHROPIC_API_KEY | Primary diagnosis model. |
SERPER_API_KEY | Live SERP results. |
CRON_SECRET | Bearer token guarding every cron endpoint. |
NEXT_PUBLIC_APP_URL | Absolute base for redirects and emails. |
ADMIN_EMAIL | Admin account for demo management. |
And the ones that decide what it costs you:
| Variable | Purpose |
|---|---|
AI_SPEND_CAP_USD | Ceiling on total recorded AI spend. Unset means no cap. Approximate by design, and fails open. |
AI_DISABLED | true stops every AI call at the single funnel they share, leaving ingestion, scoring and email running. |
GOOGLE_GEMINI_API_KEY, OPENAI_API_KEY | Links three and four of the failover chain. Skipped when unset. |
FIRECRAWL_API_KEY | JS-rendered page extraction. Falls back to Cheerio. |
Set AI_SPEND_CAP_USD before you run anything. It is the only thing
standing between a loop and your card.
The first run
Connect a Search Console property, then trigger the engine from the dashboard. The deterministic pass runs first and costs nothing: it ingests the property’s pages, computes decay scores, velocity and seasonality, and classifies each page as healthy, warning, critical or dead. You get a populated dashboard without a single model call.
Only then is a diagnosis a separate, deliberate action — and that is the one that spends money. Expect a few minutes: the pipeline searches Google live, crawls your page plus up to three ranking competitors, and generates up to 8,192 output tokens before validation.
Adapting it to something else
- A different site — nothing is hardcoded to one property. Connect a different Search Console property and the engine treats it the same.
- A different provider in the chain — providers sit behind a common
AIProviderinterface. Add or reorder entries ingetDiagnosisChain()insrc/lib/ai/chain.ts; the fallback runner does not care who is in the list. - Different thresholds — the decay window, the noise floor and the
seasonality tolerance are constants in
src/lib/engine/andsrc/lib/constants.ts, not scattered through queries. - No AI at all — set
AI_DISABLED=trueand the deterministic engine still runs end to end. That split is the whole architecture, and it holds.
The decision I defend most
The architecture and the complete SQL schema were specified before the first line of application code. The initial commit contains eleven project documents — product spec, architecture with the full schema, scope, backend algorithms, design system — and no features. The stack was then locked against drift by an explicit instruction never to substitute alternatives unasked.
Over 300+ commits later, the system still matches its day-one architecture document. That is the claim I would most want tested, and it is the one most easily checked: the first commit is in the history, and so is everything since.
On how it was built
Built with heavy AI assistance, before I decided to learn properly. It works, it runs unattended in production, and the decision to keep it here is part of the story.
Because every commit was a pair session, the git history cannot separate a human-typed line from a model-generated one, and I will not pretend otherwise. What I can defend is every decision on this page — each has a reason I can reconstruct, and several exist only because something broke in production and had to be understood.
What is not done
No automated tests and no CI — the project’s biggest gap. No paying users. Monetisation is integrated and switched off. Alerting is detected and logged but never delivered: the product finds decay and does not tell you. The quality of the diagnoses has never been systematically evaluated. These are listed in full, with what I would do first about each, in the repository README.